Nobody should have to open hundreds of agent traces one at a time

Alex Li
|
TL;DR
Opening traces one at a time works at a hundred runs. Somewhere before a thousand, coverage turns into a sample nobody chose.
Analytics solved this for events decades ago: the funnel, the cohort and the path compress millions of rows into one picture.
For agents, that picture is all agent runs drawn in one diagram, grouped by the shape of its execution path, so the places that diverge, loop or stall show up as patterns with a count.
To find failure patterns across thousands of agent runs, change the unit of work from the trace to the population. Group every run by the shape of its execution path and draw them all as one diagram. A loop, a stall or a divergence that repeats a thousand times then reads as one pattern with a count behind it.
Key facts
Databricks recommends storing MLflow traces in Unity Catalog tables, which removes the 100,000-trace limit per experiment (Databricks docs, 2026).
Snowflake Cortex Agents log threads, turns and execution spans automatically into one event table,
AI_OBSERVABILITY_EVENTS(Snowflake docs, 2026).In Snowflake's model, one turn is one OpenTelemetry trace, made of spans for planning, tool calls and responses (Snowflake docs, 2026).
The Hundred-Run Habit
You can open any agent run end to end: the prompt, every tool call, every retrieval, the answer. At a hundred runs, that is how a careful team works. You open, you understand, you fix.
Keeping the runs is the easy part now. Databricks stores MLflow traces as governed tables with no storage cap, and Snowflake writes agent spans into an event table without anyone asking. Collecting every run is solved. Seeing them is the part left open.
The Sample Nobody Chose
Volume grows faster than attention. At a few hundred runs you start skimming. Somewhere before a thousand, you open the runs someone flagged, the ones that errored, and a handful that looked odd. Coverage has quietly become a sample, and nobody chose it.
The pattern that matters tends to sit in the runs nobody opened. A retry loop that burns tokens and then succeeds. A tool call that stalls for one kind of request. Each run looks fine on its own. The problem only shows up when you see all of them. When the question finally gets asked, the hour that matters goes into a one-off script over the trace export.
If opening traces can't keep up, how do you see what the whole population is doing?
One Picture of Every Run
One picture of all runs tells you more than a thousand traces you have to open.
Draw every run in the population as one diagram, grouped by the shape of its execution path. Runs that took the same route merge into one flow. The places where runs diverge, loop or stall become visible patterns, each with a count. Every pattern shows up, including the ones that never threw an error.
Nobody should have to open them one at a time.
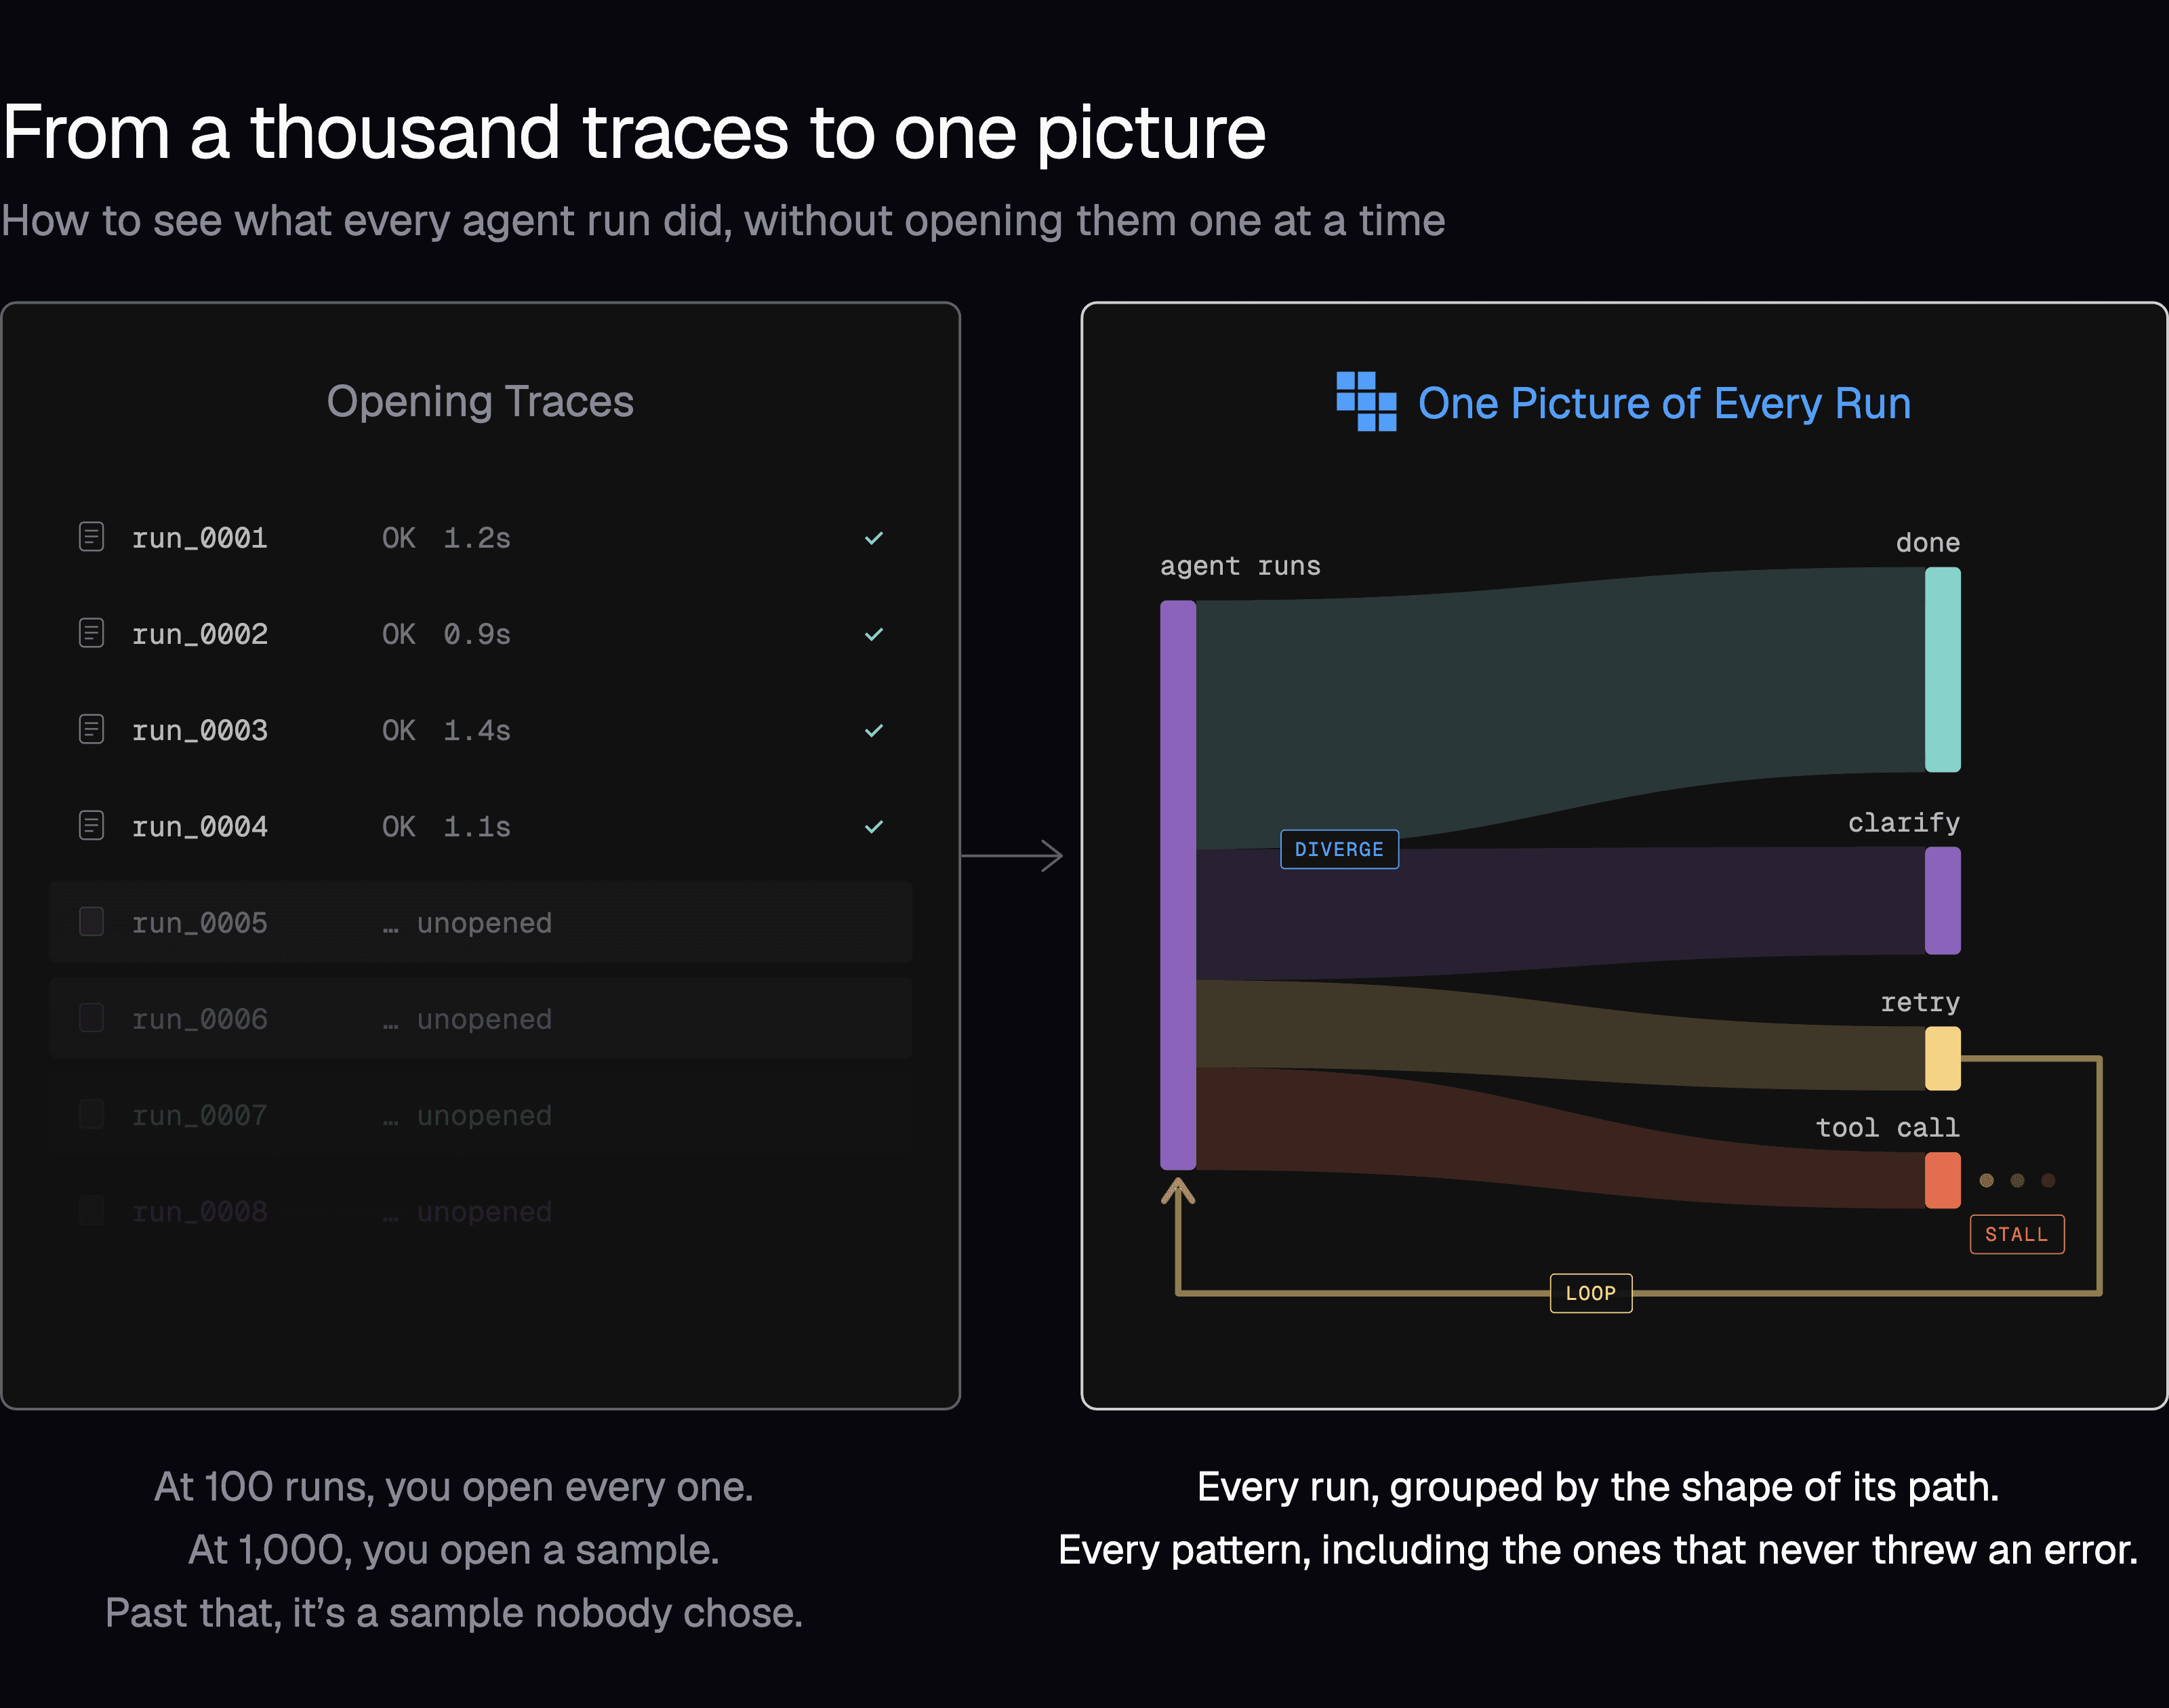
Runs you see — Opening traces: the ones you open. One picture of every run: all of them.
A failure that repeats 1,000 times — Opening traces: 1,000 separate incidents. One picture: one pattern with a count.
A retry loop that ends in success — Opening traces: reads as a success. One picture: shows as a loop in the path.
A new question — Opening traces: a new script. One picture: a new slice of the same diagram.
Where We First Saw It
We first ran into this while building our own agent. At a few hundred runs we could still open every trace, and checking quality that way was already hard. Each run made sense on its own. What we couldn't see was the same failure taking the same shape, over and over, across runs.
If opening runs one at a time is already hard at a few hundred, it stops being a method at tens of thousands a week.
What Analytics Already Solved
Product analytics hit the same wall with events. Nobody reads a raw clickstream. The funnel, the cohort and the path exist so a person can understand millions of events in a single look. Each one decides what to hide so the pattern can show.
A trace view does its own job well: it shows one run in full detail, and you still need it once you know which run to open. The gap is the step before that. My objection isn't to AI either. It's to AI handing you prose when it could hand you a shape to see the pattern with clarity. A chart is more effective than thousands of words.
What We Built
Kubit draws all agent runs as a Sankey, clustered by the shape of their execution paths. Polaris labels every span, so a failure that returns a clean status still carries a label. You can slice the diagram into funnels and cohorts to spot where runs stall. It all runs where your traces already sit, in Databricks or Snowflake, and your traces never leave your warehouse.
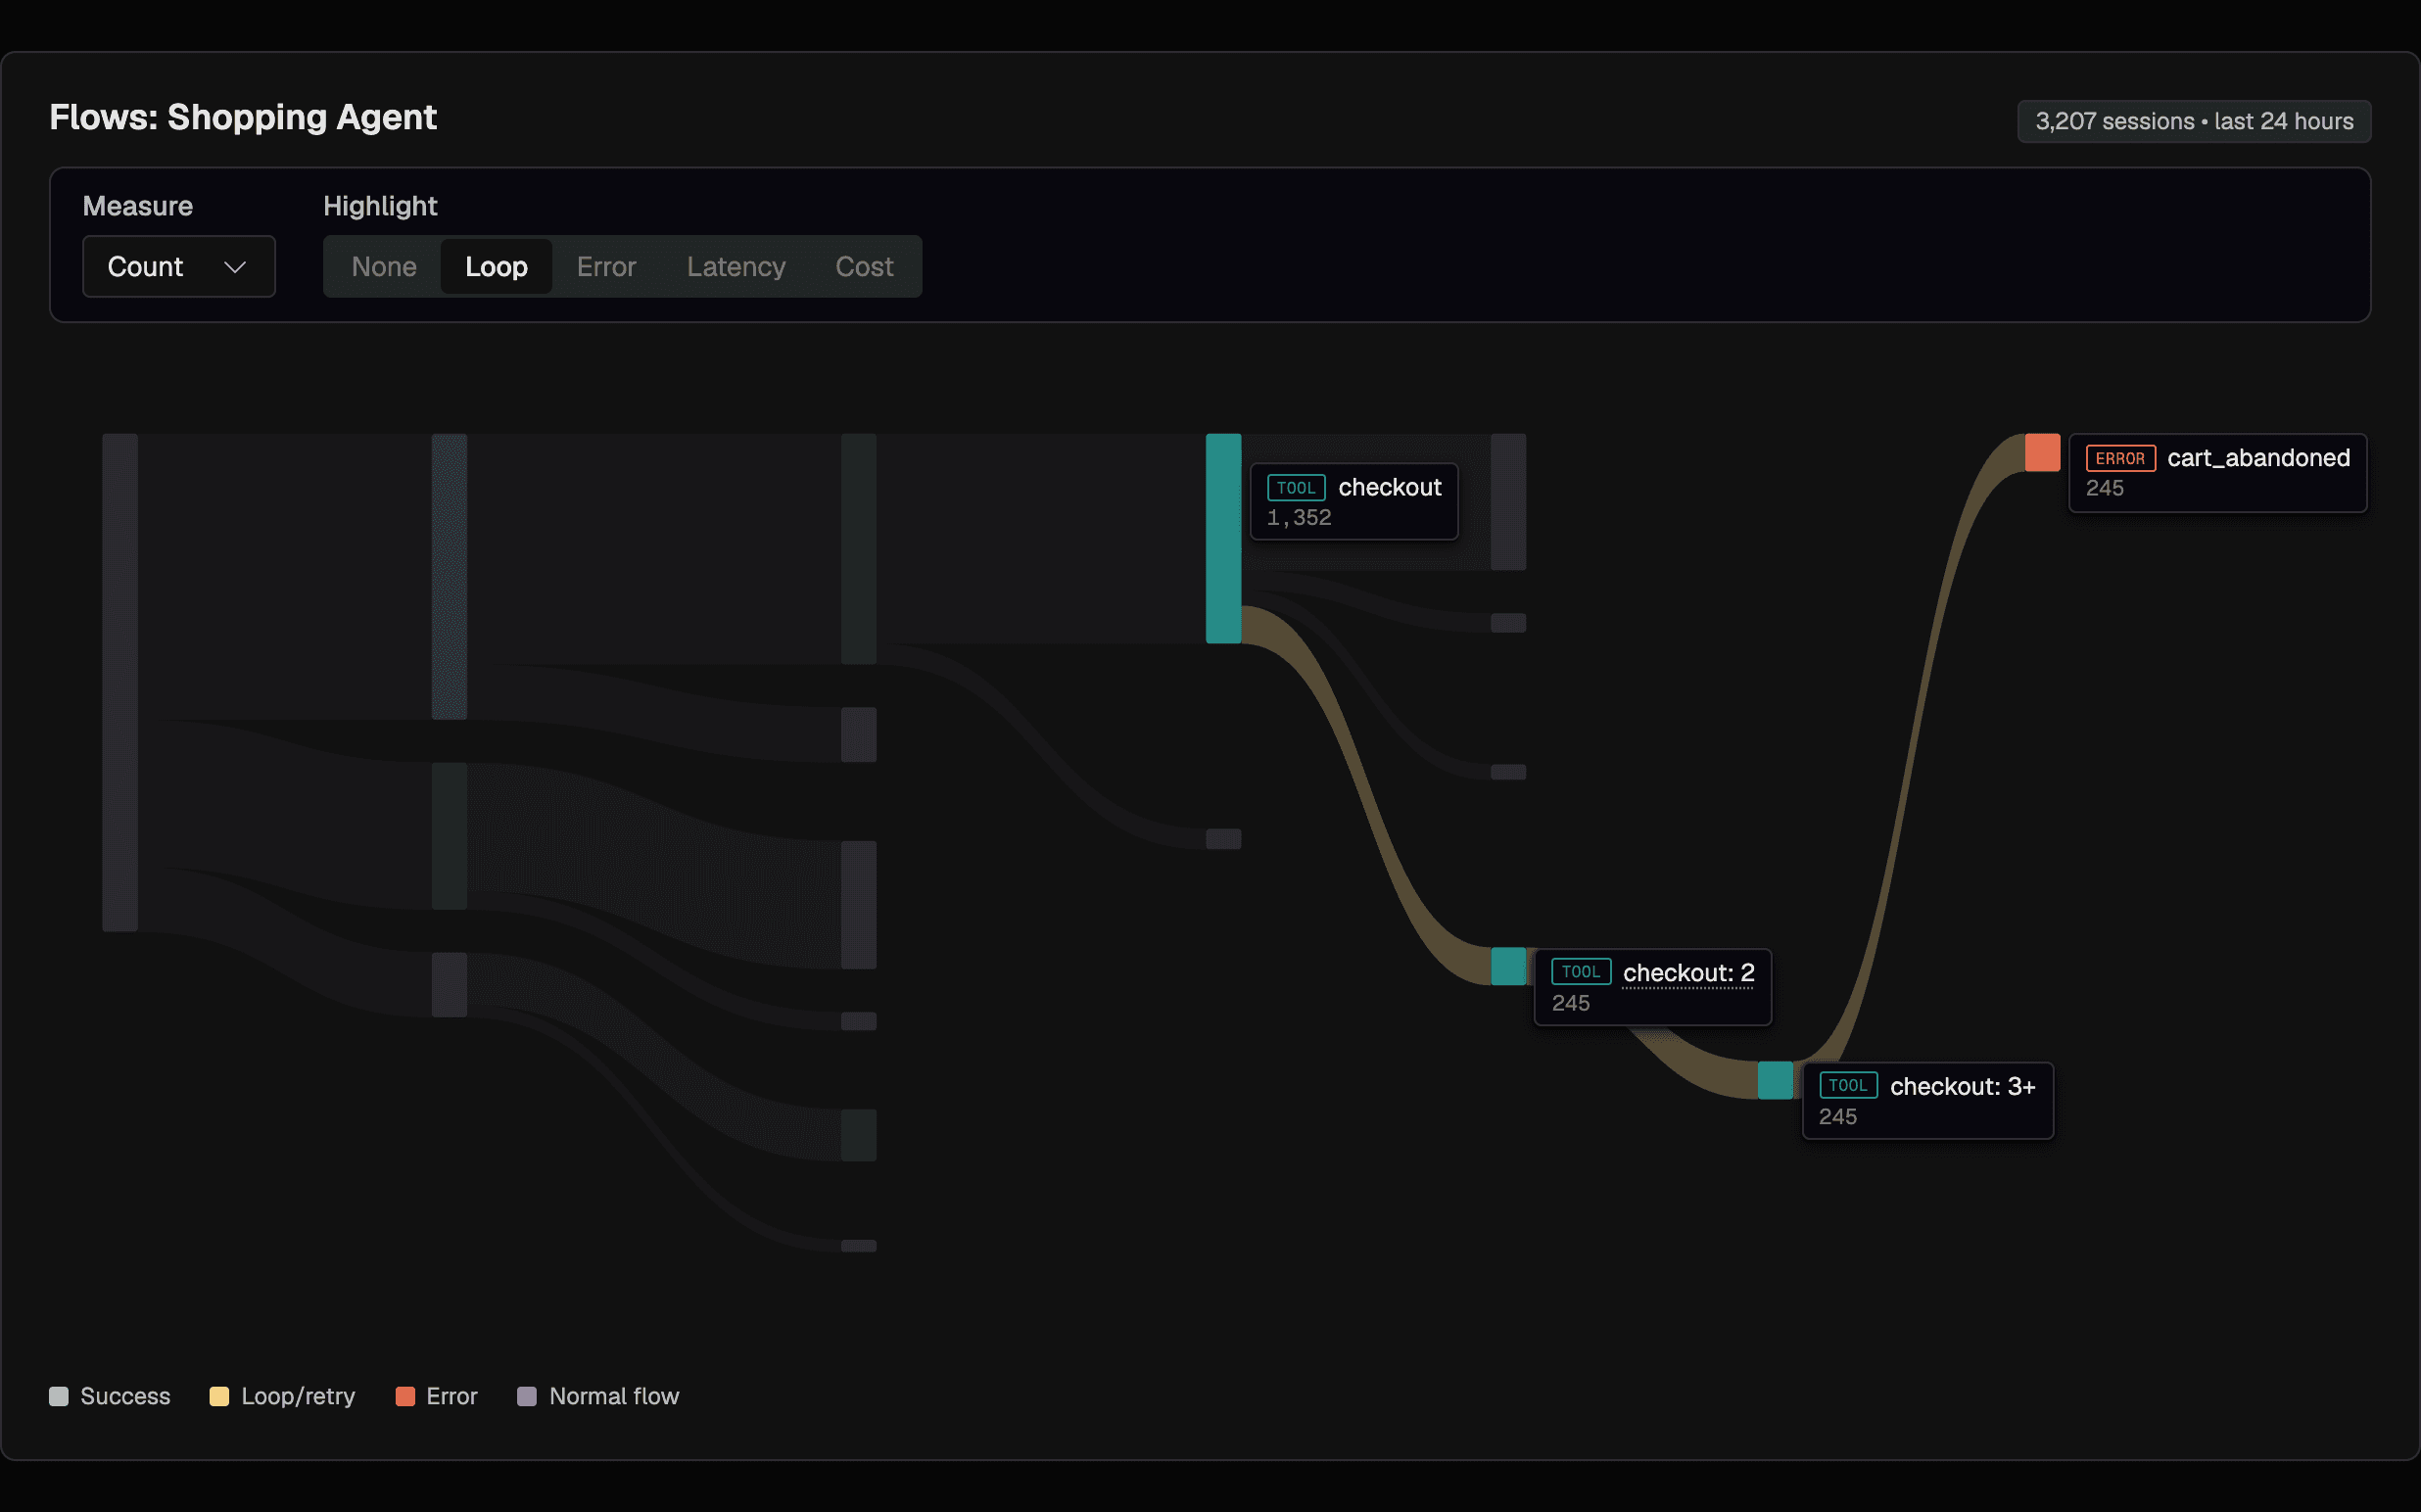
Synthetic data from the Kubit demo.
In the live demo, 3,207 sessions of a shopping agent become one diagram. The checkout retries, the product-not-found branch and the refund path each show up as a flow you can measure by count, error, latency or cost.
We're opening a first cohort of 7 teams running agents in production, with traces already in Databricks or Snowflake. Applications close October 26. Request early access.
Every week we host a live session with an engineer who runs agents in production. Follow the Kubit calendar on Luma to get each one.
FAQ
How do you find failure patterns across thousands of agent runs?
Group the runs by the shape of their execution path and look at the whole population as one diagram. Loops, stalls and divergences that repeat show up as patterns, each with a count. Rank them by how often they happen, then open only the runs that matter.
What does sampling agent traces miss?
Everything outside the sample. A failure that returns a clean status and sits in the unopened runs never gets looked at, and the coverage number becomes one nobody chooses. Grouping every run removes the need to pick which ones to open first.
What is the shape of an execution path?
It's the route a run takes through its steps: which tools it called, in what order, where it branched, where it repeated a step and where it stopped. Two runs with the same shape took the same route, even if their inputs were different.
Do I have to move my traces to see them this way?
No. Kubit queries agent traces in place, inside your own Databricks or Snowflake account. There's no SDK to install and no pipeline to build. BigQuery and ClickHouse arrive in Q4.
Table of contents
Running agents in production?
We are opening a first cohort of 7 teams. Your traces stay in your warehouse.


Summarize this post


